
Introdução: A Arte da Precisão na Usinagem de Blocos de Resfriamento de GPU
No mundo de alto risco do desempenho de PCs, onde cada quadro e cada megahertz contam, a batalha contra o calor é implacável. No centro desta guerra térmica está um componente de engenharia notável: o bloco de resfriamento de GPU. Mais do que apenas um pedaço de metal, é uma maravilha de microengenharia meticulosamente elaborada, cujo desempenho é ditado pela ciência exata de sua criação. O processo de usinagem de bloco de resfriamento de GPU não é apenas uma etapa de fabricação; é a arte fundamental que transforma matérias-primas na interface primária entre um processador gráfico em brasa e o líquido de arrefecimento que o doma. Esta arte de precisão equilibra dinâmica de fluidos, condutividade térmica e integridade mecânica, exigindo tolerâncias medidas em mícrons. A jornada de um bloco sólido de cobre ou alumínio até um complexo labirinto de canais e aletas é um testemunho da manufatura avançada, onde a qualidade do corte se traduz diretamente no silêncio, na estabilidade e na margem de overclocking de um rig de jogos ou estação de trabalho de alto desempenho.
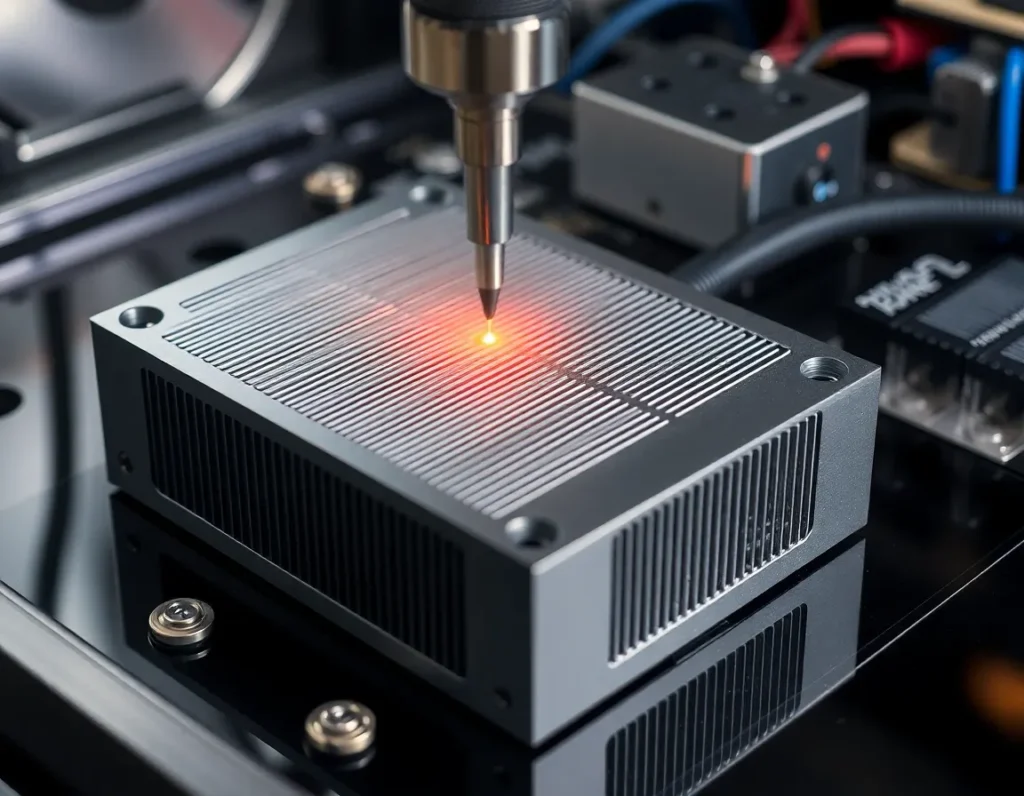
O que é um Bloco de Resfriamento de GPU? Anatomia e Função Principal
Um bloco de resfriamento de GPU, frequentemente chamado de water block em loops de refrigeração líquida personalizados, é um trocador de calor de contato direto. Sua função principal é capturar a energia térmica residual do die do processador gráfico (GPU), bem como de componentes associados como VRAM e VRMs, e transferi-la eficientemente para um refrigerante em fluxo. Diferentemente dos volumosos coolers a ar, ele consegue isso por meio de contato íntimo metal-metal e caminhos de fluxo de líquido otimizados.
Anatomicamente, um bloco de GPU típico de cobertura total consiste em várias camadas principais:
- Placa Fria: Este é o coração do bloco. É uma placa de metal plana e usinada que fica diretamente sobre o chip da GPU. Sua face inferior apresenta um arranjo precisamente usinado de microaletas, pinos ou canais que criam uma vasta área de superfície para transferência de calor para o refrigerante.
- Placa de Jato de Impacto ou Distribuição: Frequentemente integrada ao design da placa fria ou como uma camada separada, este componente gerencia o fluxo do refrigerante. Ele usa uma série de entradas e microbicos para direcionar forçadamente o refrigerante para as áreas mais quentes da placa fria, quebrando camadas-limite e maximizando a troca térmica.
- Carcaça Principal ou Placa Superior: Este componente estrutural veda a câmara de resfriamento. Ele contém as portas de entrada e saída para os tubos de refrigerante e frequentemente apresenta elementos estéticos como janelas de acrílico ou designs intrincados fresados em CNC. Ele deve ser rígido o suficiente para suportar a pressão de fixação e a pressão interna do fluido sem se deformar.
- Hardware de Montagem e Interface Térmica: Um sistema de parafusos, placas traseiras e espaçadores garante uma pressão de montagem uniforme e segura. Entre a placa fria e o die da GPU, é aplicada uma pasta ou almofada térmica de alto desempenho para preencher imperfeições microscópicas e garantir uma condução térmica ideal.
Em essência, o bloco é um sistema selado e pressurizado de microcanais, onde o refrigerante é forçado a absorver calor o mais rapidamente possível antes de ser levado a um radiador. A eficiência de todo esse sistema nasce no processo de usinagem.
O Papel Crítico da Usinagem no Desempenho do Resfriamento Líquido
A diferença de desempenho entre uma solução de resfriamento líquido mediana e uma excepcional é quase inteiramente forjada durante a usinagem. Esta etapa determina as propriedades físicas fundamentais que regem o desempenho térmico e hidráulico. Três fatores dependentes da usinagem são primordiais: planicidade da superfície, geometria dos canais e integridade da vedação.
Primeiro, a planicidade da superfície de contato da placa fria é inegociável. Um die de GPU normalmente tem apenas algumas centenas de milímetros quadrados de área. Qualquer empenamento ou irregularidade microscópica na placa fria cria lacunas de ar, que são péssimos isolantes térmicos. A usinagem de alta precisão e o subsequente polimento garantem uma superfície quase perfeitamente plana, permitindo que o material de interface térmica forme uma camada fina e consistente para uma transferência de calor sem obstáculos.
Segundo, a geometria das estruturas internas de resfriamento — as aletas, pinos e canais — é um produto direto da capacidade de usinagem. A densidade, altura e espessura dessas características definem o desempenho térmico e a resistência ao fluxo do bloco. Microaletas mais finas e densas oferecem mais área de superfície para troca de calor, mas restringem o fluxo do refrigerante, exigindo mais pressão da bomba. O processo de usinagem deve esculpir essas características delicadas com bordas afiadas e limpas e dimensões consistentes; rebarbas ou variações podem criar zonas mortas de fluxo, aumentar a queda de pressão e aprisionar bolhas de ar, prejudicando severamente a eficiência.
Por fim, a usinagem define as superfícies de vedação. As faces de acoplamento entre a placa fria, os sulcos do O-ring e a placa superior devem ser impecavelmente lisas e paralelas. Qualquer imperfeição aqui pode levar a vazamentos, que são catastróficos em um PC. A precisão da profundidade e largura do canal do O-ring garante que o vedante de silicone se comprima corretamente, criando uma barreira confiável e duradoura contra o refrigerante de alta pressão. Em resumo, a usinagem transforma um projeto teórico em um objeto físico que deve se destacar simultaneamente em condução térmica, dinâmica de fluidos e confiabilidade mecânica.
Principais Processos de Usinagem: Fresamento CNC, Perfuração e Acabamento
A criação de um bloco de resfriamento para GPU é dominada pela usinagem por Controle Numérico Computadorizado (CNC), um processo de manufatura subtrativa no qual um software pré-programado dita o movimento de ferramentas e máquinas de fábrica. Isso permite a precisão extrema e a repetibilidade necessárias.
Fresamento CNC
O fresamento CNC é o processo principal. Um bloco de metal (a “peça de trabalho”) é fixado a uma mesa móvel, e uma ferramenta de corte rotativa de múltiplos gumes remove material. Para blocos de GPU, isso acontece em múltiplos estágios e eixos. O fresamento de 3 eixos é comum para geometrias mais simples, mas o fresamento de 5 eixos é frequentemente empregado para blocos complexos de cobertura total, com canais integrados e pontos de montagem em múltiplos planos. O processo de fresamento cria os sulcos do O-ring, as roscas das portas, os furos dos parafusos de montagem, a cavidade principal do refrigerante e as características estéticas externas. A operação de fresamento mais crítica é a criação do conjunto de microaletas na placa fria. Isso requer microferramentas especializadas, muitas vezes com menos de 1 mm de diâmetro, movendo-se em alta velocidade com vibração mínima para evitar a quebra da ferramenta e garantir a precisão dimensional.
Perfuração CNC
Enquanto o fresamento usa cortadores rotativos, a perfuração cria furos redondos. Na fabricação de blocos, a perfuração CNC é usada com precisão para as portas de entrada e saída que se conectam aos tubos de refrigerante. Esses furos devem ser perfeitamente perpendiculares e acabados suavemente para garantir uma boa vedação com os conectores. A perfuração profunda também pode ser usada para criar passagens verticais internas em projetos de blocos multicamadas para distribuição do refrigerante.
Processos de Acabamento
Após a remoção do metal principal, várias etapas de acabamento são cruciais:
- Rebarbação: Manual or automated removal of tiny raised edges or “burrs” left by cutting tools, especially critical inside fluid channels to ensure smooth laminar flow.
- Lapping/Sanding: The GPU contact surface is often hand-lapped or machine-sanded on a perfectly flat plate with progressively finer abrasives. This achieves the mirror-flat finish necessary for optimal thermal contact.
- Cleaning: Intensive ultrasonic cleaning in specialized solutions removes all machining oil, metal dust, and abrasive particles from the intricate internal channels. Any residue would contaminate the coolant and degrade performance.
- Surface Plating (if applicable): For blocks using nickel-plated copper, the machined copper component undergoes an electrochemical plating process to apply a layer of nickel for corrosion resistance and aesthetics, before a final cleaning.
This symphony of CNC-controlled and manual finishing processes ensures the block is not just shaped correctly, but is hydraulically smooth, thermally optimal, and impeccably clean.
Material Selection for GPU Cooling Blocks: Copper, Nickel, and Aluminum
The choice of material is a fundamental engineering decision in usinagem de bloco de resfriamento de GPU, directly trading off between thermal performance, corrosion resistance, weight, cost, and manufacturability.
Copper (Cu)
Copper is the undisputed king of thermal performance for cooling blocks. With a thermal conductivity of approximately 385-400 W/(m·K), it transfers heat from the GPU die to the coolant more effectively than any other practical metal. It is also relatively easy to machine, allowing for the creation of sharp, fine micro-fins. Nearly all high-performance blocks use a copper cold plate. Its primary drawbacks are its propensity to oxidize (develop a patina) and its susceptibility to galvanic corrosion if paired with aluminum in the same loop without proper inhibitors. It is also dense and expensive.
Nickel (Ni) – Almost Always a Plating
Pure nickel blocks are exceedingly rare due to cost and machining difficulty. Instead, nickel is used as an electroplated surface layer over a copper substrate. Nickel plating, typically 5-15 microns thick, serves two main purposes: corrosion resistance and aesthetics. It forms a hard, stable barrier that protects the underlying copper from oxidation and galvanic corrosion. It also provides the signature shiny, silver finish favored by many enthusiasts. The plating must be applied evenly and adhere perfectly; any porosity or flaking can expose the copper and lead to localized corrosion. While nickel has lower thermal conductivity (~90 W/(m·K)) than copper, the layer is so thin that its impact on overall thermal resistance is minimal.
Aluminum (Al)
Aluminum, with a thermal conductivity around 160-200 W/(m·K), is a distant second to copper in pure thermal performance. However, it is significantly lighter, cheaper, and easier to mass-produce through casting and machining. Its use is almost exclusively in all-in-one (AIO) liquid coolers and entry-level cooling solutions where cost and weight are primary constraints. A critical rule in liquid cooling is to never mix aluminum and copper components in the same loop without specialized coolant, as the difference in electrochemical potential will cause rapid galvanic corrosion, clogging fins and destroying blocks.
The material selection directly influences the machining strategy. Softer copper allows for more aggressive cuts and finer details but requires care to avoid gouging. Aluminum machines quickly and cleanly but can be gummy, requiring sharp tools and specific feed rates. The chosen material ultimately sets the ceiling for the block’s potential thermal efficiency, which the machining process then strives to fully realize.
Advanced Techniques: Micro-Fin Structures and Jet Impingement Plates
Pushing beyond the foundational milling and drilling of a basic cold plate and channels lies the realm of advanced usinagem de bloco de resfriamento de GPU. Here, the precision of modern CNC technology is leveraged not just to create a path for coolant, but to engineer microscopic turbulence and direct, high-velocity fluid impacts that dramatically enhance heat extraction. Two techniques stand at the forefront of high-performance cooling: micro-fin arrays and jet impingement plates.
Micro-Fin Arrays
Imagine replacing the smooth floor of a coolant channel with a dense forest of microscopic fins. This is the principle behind micro-fin arrays. Using specialized micro-tools, often with diameters between 0.2mm and 0.5mm, CNC machines carve hundreds of these tiny fins directly into the copper or nickel-plated copper cold plate. The purpose is multifaceted. First, they drastically increase the surface area in direct contact with the coolant, providing more “skin” for heat to transfer into the fluid. Second, and more critically, they disrupt laminar flow—the smooth, layered movement of liquid that is poor for heat transfer. The fins force the coolant into a turbulent state, constantly mixing the hotter fluid near the metal with the cooler fluid in the center of the channel. This turbulence ensures the coolant’s thermal capacity is fully utilized before it exits the block. Machining these fins requires exceptionally rigid machines, high spindle speeds, and sophisticated toolpath strategies to prevent tool deflection and breakage, representing a pinnacle of precision manufacturing in cooling solutions.
Jet Impingement
While micro-fins work on creating turbulence across a wide area, jet impingement is a technique of targeted, aggressive cooling. In this design, the cooling block incorporates a secondary plate (the jet plate) positioned between the inlet and the cold plate. This jet plate is machined with an array of precise, small-diameter holes. As pressurized coolant is forced through these holes, it transforms into multiple high-speed jets that shoot directly onto the hottest zones of the cold plate—typically the areas aligned with the GPU die’s cores. This violent impact scrubs away the insulating boundary layer of hotter fluid that naturally clings to the metal surface, achieving some of the highest possible heat transfer coefficients in liquid cooling. The spent fluid then flows sideways into surrounding micro-fin channels for further heat dissipation before exiting. Machining the jet plate requires extreme accuracy in hole diameter, spacing, and alignment to ensure even coverage and optimal pressure distribution across the entire GPU die.
The implementation of these advanced features is a direct response to the concentrated heat flux of modern GPUs. By combining micro-fins for broad-area efficiency with jet impingement for spot-cooling intensity, block manufacturers can design solutions that keep pace with thermal design power (TDP) figures exceeding 500 watts. The transition from simple channels to these engineered structures marks the difference between a cooling block that merely works and one that defines the cutting edge of thermal performance.
Quality Control and Testing: Ensuring Flatness, Leak-Proof Seals, and Thermal Efficiency
The most intricately machined cooling block is a failure if it leaks, doesn’t make proper contact, or performs poorly. Therefore, rigorous quality control and testing protocols are integral to the manufacturing process, acting as the final gatekeeper before a block reaches a customer’s high-end PC.
Dimensional and Surface Flatness Verification
The flatness of the cold plate is non-negotiable. Even a microscopic convex or concave bow can create air gaps between the block and the GPU die, crippling thermal transfer. After machining, blocks undergo precise flatness testing using tools like dial indicators on surface plates or, more commonly, optical flatness scanners. These scanners use light interference patterns to create a topographical map of the surface, measuring deviations down to microns (µm). A typical high-performance block specification demands flatness within 0.05mm or less across the entire IHS contact area. Any block outside this tolerance is re-lapped (precision sanded flat) or scrapped.
Leak Testing Under Pressure
Every single cooling block must be validated as leak-proof. This is not a simple visual check. Blocks are subjected to pressure decay testing. The block’s ports are sealed, and it is pressurized with air or an inert gas to a level significantly higher than normal loop operating pressure (e.g., 1.5 to 2 bar). The system then monitors for any pressure drop over a set period. A drop indicates a leak, often from an imperfect O-ring groove, a micro-crack from machining stress, or a faulty seal in a threaded fitting. Blocks that pass are clean and dry; those that fail are diagnosed and repaired if possible.
Thermal Performance Benchmarking
While dimensional checks ensure the block can be installed, thermal testing proves it works. Manufacturers use standardized test benches to quantify performance. A thermal test head (simulating a GPU die) generates a known, controlled amount of heat. The block is mounted with a standardized thermal paste and torque, and coolant at a set temperature and flow rate is passed through it. Sensors measure the temperature difference between the coolant (∆T) and the heat source. This data is used to calculate thermal resistance (in °C/W)—the ultimate metric of a block’s efficiency. Lower resistance means better performance. This testing validates design choices, machining quality of micro-features, and ensures consistency from batch to batch. It’s the final, definitive proof that the machining and assembly processes have come together to create a product that performs as engineered.
Custom vs. Mass-Produced: Machining for Enthusiasts and OEMs
The world of GPU water blocks splits into two distinct paradigms, each with its own machining philosophy, scale, and economic drivers: mass production for original equipment manufacturers (OEMs) and the custom market for PC enthusiasts.
Mass-Produced OEM Blocks
This domain is defined by scale, cost-efficiency, and reliability for a broad market. Think of the cooling solutions pre-installed on liquid-cooled graphics cards from major brands or standard all-in-one (AIO) coolers. Here, machining is highly optimized for volume. Processes often involve casting the main block body from aluminum (for AIOs) or copper, then using high-speed CNC machining centers in automated production lines to finish critical surfaces, drill ports, and mill channel patterns. Tolerances are tight but focused on repeatability over absolute perfection. The design is usually simplified for manufacturability—wider channels, fewer ultra-fine micro-fins—to maximize yield and minimize machining time. The primary goal is to produce thousands of identical, reliable units at a low cost per unit, meeting a guaranteed performance standard for the OEM’s product.
Custom and Enthusiast-Grade Blocks
At the opposite end of the spectrum lies the custom market, catering to the modding and extreme performance community. Here, the focus shifts from cost to ultimate performance, aesthetics, and compatibility with specific, often rare, graphics card models. Machining is done in smaller batches or even as one-off commissions. Manufacturers like EKWB, Watercool, and Bitspower use full CNC machining from solid copper or brass billets, even for complex shapes, avoiding casting entirely for superior material integrity and detail. This allows for daring designs: intricate, deep micro-fin arrays, integrated RGB light channels, and acrylic tops with elaborate milled logos. Tolerances are obsessive, and finishing processes like meticulous hand-polishing or multi-layer nickel plating are common. The machining runs are slower, the material waste is higher, and the cost reflects it. This sector thrives on innovation, quickly adapting to new GPU releases and pushing the boundaries of what’s possible in usinagem de bloco de resfriamento de GPU for those who view cooling as a centerpiece of their build.
The dichotomy ensures that liquid cooling remains accessible at an entry level while providing a pinnacle to aspire to for enthusiasts. Both sectors rely on precision machining, but they apply its capabilities to solve fundamentally different business and engineering challenges.
Resumo dos Pontos Principais
GPU cooling block machining is a sophisticated discipline that transforms raw metal into a critical thermal management component. It begins with selecting the right material—copper for its unmatched conductivity, often nickel-plated for corrosion resistance, or aluminum for cost-sensitive applications, with careful avoidance of galvanic corrosion. The core processes of CNC milling, drilling, and finishing create the fundamental structure: the cold plate for die contact and the channels for coolant flow.
Advanced techniques elevate performance. Micro-fin arrays, machined with tiny tools, create turbulent flow and massive surface area for efficient heat transfer. Jet impingement plates use precisely drilled holes to blast coolant directly onto hot spots, disrupting the thermal boundary layer for maximum cooling intensity. These features are direct responses to the extreme heat flux of modern graphics processors.
None of this precision matters without rigorous quality control. Every block must pass stringent tests for cold plate flatness (within hundredths of a millimeter), undergo pressurized leak testing, and be thermally benchmarked to verify its performance against a calculated thermal resistance metric. This ensures reliability and efficacy.
Finally, the machining approach diverges based on the market. Mass-produced blocks for OEMs prioritize high-volume, cost-effective manufacturing with reliable performance. In contrast, the custom enthusiast market employs full-CNC machining from solid billets to achieve peak thermal performance, intricate aesthetics, and support for niche hardware, representing the artisanal peak of the craft. Together, these facets of machining make liquid cooling a viable and high-performance solution for GPUs at every level of the computing world.
Frequently Asked Questions (FAQ)
What is the single most important factor in GPU block performance?
While material and design are crucial, the quality of the contact between the block’s cold plate and the GPU die is paramount. This is determined by the machining flatness of the plate and the mounting pressure. Even the best copper block with micro-fins will underperform if the surface isn’t perfectly flat, creating insulating air gaps. This is why premium blocks undergo such rigorous flatness verification.
Can I machine my own custom GPU water block?
Technically yes, but it is an exceptionally challenging project requiring advanced machining skills and equipment. You need a capable CNC mill, micro-tools for fin structures, precise CAD/CAM programming, and the ability to perform leak and pressure testing. For most, purchasing a professionally machined block designed for their specific GPU model is far more practical, reliable, and cost-effective.
Why are some blocks made from a single piece of metal (monoblock) for the GPU and VRM, while others are separate?
This is a design and machining choice. A monoblock cools the GPU, VRM (voltage regulation modules), and sometimes memory with one unit, offering a clean aesthetic and simplified loop. However, it is larger, more complex to machine, and specific to one graphics card model. Separate blocks offer modularity and may allow for more focused cooling on the GPU die itself, but require more fittings and tubing. Machining a monoblock involves a more complex, multi-level milling operation to create different channel depths for various components.
How does nickel plating affect performance and machining?
Nickel plating is applied electrochemically after the copper block is machined. It adds a thin, protective layer that prevents copper oxidation (tarnishing) and improves compatibility with coolants and other loop metals. The plating slightly reduces thermal conductivity compared to bare copper, as nickel is less conductive, but the difference in a thin layer is minimal (1-3°C typically). The machining itself is done on the copper substrate, as plating would be destroyed by cutting tools.
Is a block with more, finer coolant channels always better?
Not necessarily. While dense micro-fins increase surface area, they also increase flow restriction (pressure drop). Your pump must be strong enough to overcome this restriction and maintain adequate flow rate through the entire loop. A balance must be struck. A block with extreme fin density might outperform on a test bench with a powerful standalone pump, but could cause overall loop failure in a system with a weaker pump. Good block design optimizes for heat transfer and manageable flow restriction.
How long does it take to machine a single high-end GPU water block?
For a custom, enthusiast-grade block machined from a solid copper billet, the total CNC machining time can range from 45 minutes to over 2 hours per block, depending on the complexity of the fin structure, top design, and logos. This doesn’t include time for plating, polishing, cleaning, assembly, and testing. Mass-produced blocks have cycle times measured in minutes due to optimized toolpaths and often starting from pre-cast near-net shapes.